Dunning–Kruger Effect: What the Research Actually Shows—and What the Internet Gets Wrong
The original finding, the statistical critiques, the replication debate, and the practical lesson: calibration matters more than confidence.
The Dunning–Kruger effect is one of psychology’s most famous internet ideas—and one of the most oversimplified. The popular version says that incompetent people are highly confident because they are too incompetent to recognize their incompetence. The original 1999 research was more specific: people who performed poorly on certain tasks also showed poor calibration when estimating their own performance.
The effect has since become a meme about stupidity. That is where trouble begins. Later researchers have argued that some classic Dunning–Kruger plots can be partly produced by statistical artifacts such as regression toward the mean and the better-than-average effect. Other work still finds small effects under some conditions. The most accurate conclusion is not that the phenomenon is “fake” or universally huge. It is that self-assessment is difficult, especially when the skills needed to perform and evaluate performance overlap.
1. What Kruger and Dunning actually found
In the original studies, participants completed tests involving humor, grammar, and logic, then estimated their performance. Lower-performing participants substantially overestimated their percentile rank. The authors argued that deficits in skill could create a “double burden”: poor performance plus reduced ability to recognize errors.
Importantly, the finding concerned calibration between objective performance and self-assessment. It was not a general law stating that the least competent person is always the most confident person in every domain.
2. Why the famous graph can mislead
Researchers later pointed out that grouping people into performance quartiles and comparing actual versus estimated scores can produce patterns partly because of mathematical constraints. Measurement error and regression toward the mean can make extreme groups appear to move inward on a second measure.
Gignac and Zajenkowski argued in 2020 that much of the classic effect could be statistical artifact in intelligence data. A later reanalysis using different data found a statistically significant effect but described it as small. The debate is useful because it forces a distinction between a memorable visual pattern and the size of the underlying psychological mechanism.
3. Metacognition is the deeper topic
Metacognition is thinking about one’s own thinking: monitoring knowledge, uncertainty, errors, and performance. Accurate self-assessment requires information. Beginners may not know which features distinguish a good answer from a bad one. Experts have richer error-detection tools, although experts can also be overconfident.
This is why feedback quality matters. A person can remain confidently wrong for years in an environment that provides weak, delayed, political, or ambiguous feedback.
4. Where the idea is genuinely useful
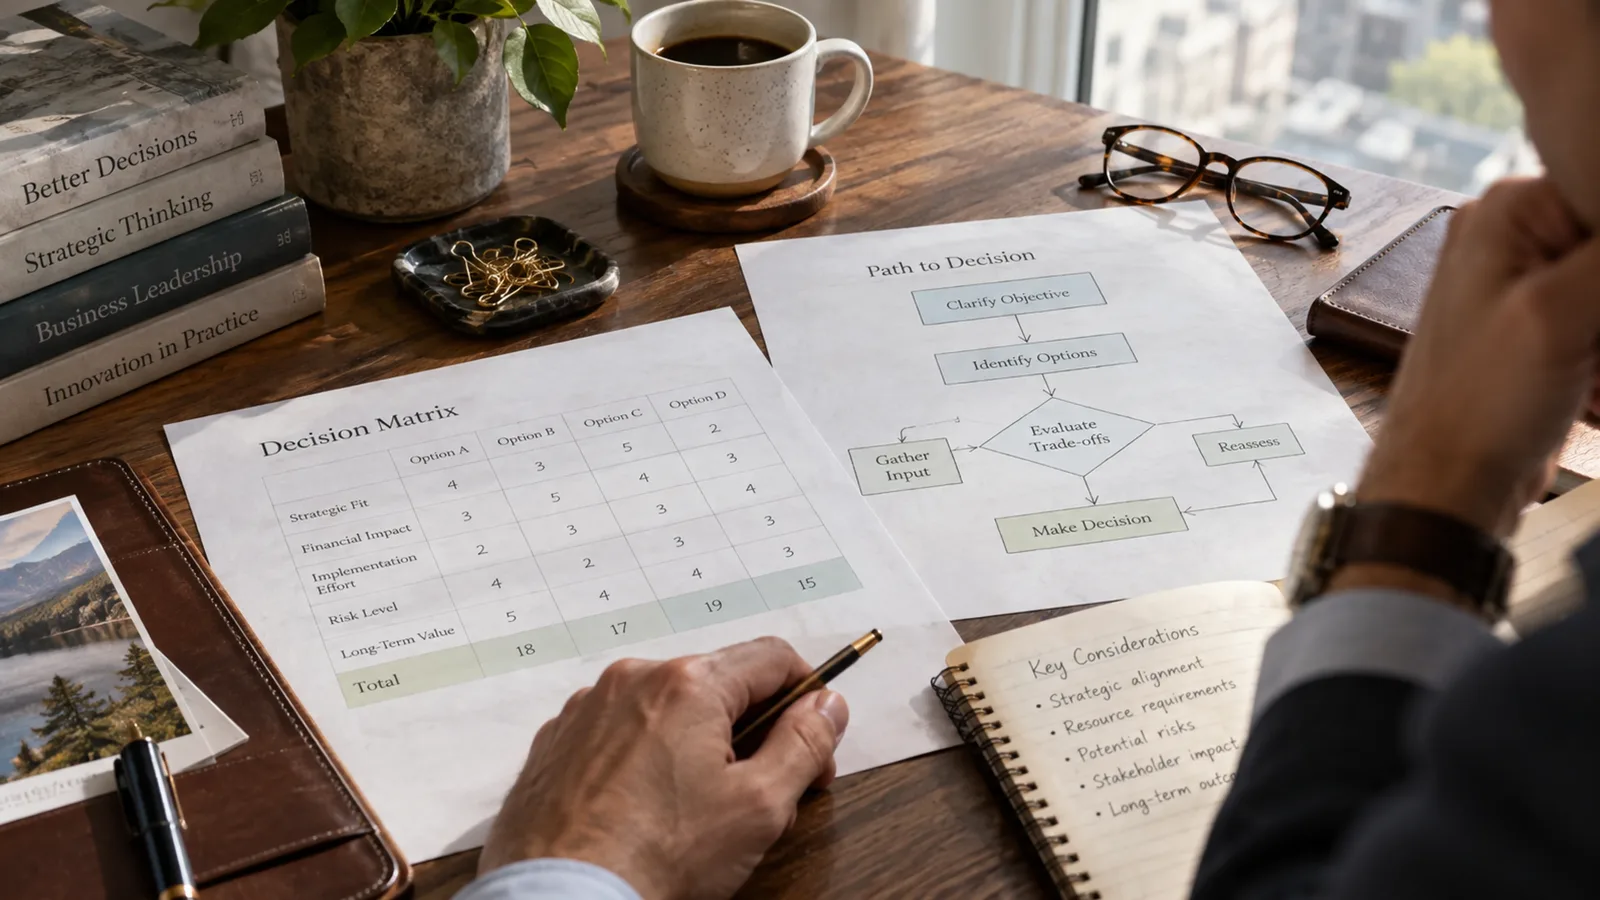
The practical value is not in ranking other people’s intelligence. It is in designing systems that improve calibration. Forecasting tournaments, prediction logs, testable hypotheses, scored practice, postmortems, and objective performance metrics create feedback loops between confidence and reality.
5. Confidence and competence are separate variables
A confident person can be competent or incompetent. A doubtful person can be competent or incompetent. Confidence is a psychological state; competence is performance relative to a standard. Treating confidence as proof of ability creates a halo effect. Treating humility as proof of ability creates the opposite error.
6. Why experts can still be miscalibrated
Expertise is often domain-specific. A brilliant surgeon can be an ordinary investor. A successful founder can misunderstand macroeconomics. Status can also reduce corrective feedback because people become less willing to challenge high-ranking individuals. Expertise therefore needs boundaries.
7. How to improve calibration
- Make predictions before seeing outcomes.
- Attach probabilities, not vague confidence words.
- Track results over time.
- Seek feedback from people who can evaluate the relevant skill.
- Use blind tests or objective benchmarks when possible.
- Separate identity from accuracy so being wrong is psychologically cheaper.
The mature lesson from Dunning–Kruger research is not “stupid people think they are smart.” It is that self-knowledge is an empirical problem. Confidence should be calibrated against reality, and calibration improves when environments provide clear, repeated, honest feedback.
8. Why beginners can improve rapidly once standards become visible
A novice often lacks a detailed representation of quality. Early training can therefore improve both performance and evaluation simultaneously. Once the person learns what good work looks like, previous mistakes become easier to see. This creates the uncomfortable but productive phase where confidence may fall while competence rises.
That pattern is one reason real learning can feel discouraging. Greater knowledge reveals complexity. The solution is not to protect confidence from evidence; it is to interpret better calibration as progress.
9. The better-than-average effect is related but different
People often rate themselves above average on desirable traits, especially when the trait is ambiguous. This can contribute to the visual pattern associated with Dunning–Kruger, but it is a broader self-evaluation bias. Separating the two matters because overconfidence does not automatically imply a metacognitive deficit specific to low performers.
10. Domain specificity
Calibration should be measured within a domain. Someone may accurately assess programming ability and poorly assess negotiation skill. General labels such as “smart” or “incompetent” collapse multiple skills into one identity judgment. Better analysis asks what task, what standard, what feedback history, and what confidence measure are involved.
11. Organizational consequences of poor calibration
Teams suffer when confidence determines influence more strongly than accuracy. Loud certainty can win meetings even when forecasts are weak. Organizations can counter this by scoring predictions, using pre-mortems, assigning devil’s advocates, and giving domain experts room to express calibrated uncertainty without being punished for sounding less confident.
12. Build a calibration dashboard for yourself
- Write a probability for important predictions.
- Record the date and evidence used.
- Score the outcome later.
- Track where you are systematically too confident or too cautious.
- Compare calibration across domains.
- Update decision rules based on repeated error patterns.
The deepest practical lesson is humility with measurement. You do not need to assume that ignorance creates extreme arrogance in every case. You only need to accept that self-assessment is fallible—and design feedback that makes it better.
A Real-World Application
A junior analyst confidently predicts a market move and happens to be right twice. Without a scoring system, confidence may rise faster than skill. A forecast log changes the environment: probabilities are written in advance, outcomes are scored, and calibration becomes visible. The system teaches humility without requiring humiliation.
Frequently Asked Questions
Does Dunning–Kruger mean stupid people are the most confident?
No. That slogan overstates the research. The original work concerned calibration errors among low performers on specific tasks, and later research debates how large and general the effect is.
Is the effect statistically disputed?
Yes. Some researchers argue classic plots are substantially influenced by regression to the mean and other statistical features. Other analyses still find small effects. The magnitude and conditions remain important parts of the debate.
What is metacognition?
It is the ability to monitor and evaluate one’s own thinking and performance—knowing what you know, what you do not know, and how reliable your judgment is.
How do you improve calibration?
Make explicit predictions, attach probabilities, use objective feedback, track results, and review where confidence systematically exceeds or falls below accuracy.
13. Confidence intervals are psychologically unfamiliar
People prefer point estimates: “I am good at this” or “there is a 70 percent chance.” Real uncertainty is a range. Measurement error, task variability, and changing conditions mean performance is not perfectly stable. Thinking in intervals makes overconfidence harder because it forces acknowledgment of plausible error.
14. Feedback must be diagnostic to improve metacognition
Not all feedback teaches. Praise without criteria says little about accuracy. Criticism without explanation can produce defensiveness. Diagnostic feedback links outcomes to specific decisions and shows what a better response would have looked like. That is the kind of feedback that improves both skill and self-assessment.
15. Social status can corrupt calibration
As people gain rank, subordinates may become less willing to contradict them. Success also creates a history of positive outcomes that can be overattributed to skill. The combination—less corrective feedback plus a successful past—can make calibration worse even for highly competent people.
Senior leaders therefore need institutionalized disagreement: red teams, independent reviews, forecast scoring, and people whose role protects them for saying “this is wrong.”
16. Why the meme survives
The popular version of Dunning–Kruger is emotionally satisfying because it explains why someone we consider incompetent can still be confident. It also flatters the observer: recognizing the effect feels like evidence of superior insight. That social usefulness helps the meme spread even when the research is more nuanced.
17. The better question is not “who has Dunning–Kruger?”
Ask instead: where is confidence poorly calibrated, and what feedback could improve it? This reframes the concept from an insult into a measurement problem. The same method can reveal underconfidence among skilled people, not just overconfidence among weaker performers.
Calibration is valuable because decisions depend not only on what you believe but on how strongly you believe it. Improving that second layer is one of the most practical forms of intellectual discipline.
Related Reading
Sources & Research Notes
This article distinguishes established findings from interpretation. Foundational studies are useful, but individual effects vary by context, measurement, sample, and replication quality. The links below are included so readers can inspect the underlying research directly.